How to Index Tier 2 Backlinks: A Practical SEO Guide
Learn why secondary backlinks fail to index and discover a practical workflow to crawl and index Tier 2 links to maximize your link-building ROI.
What Are Tier 2 Backlinks and Why Do They Matter?
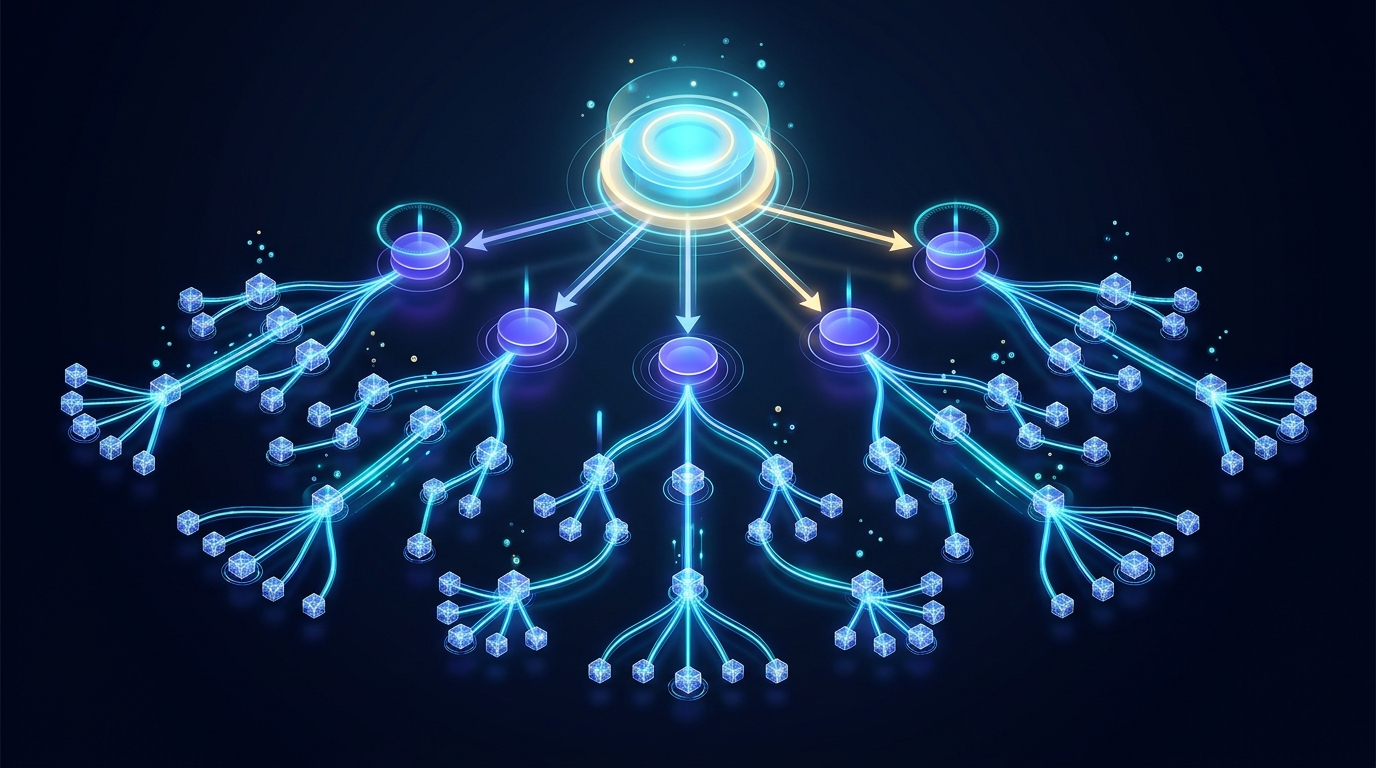
In tiered link architecture, backlinks are categorized by their structural distance from your target website. Tier 1 backlinks point directly to your primary pages—such as editorial guest posts, earned industry coverage, or niche resource citations. Tier 2 backlinks point to those Tier 1 pages rather than your primary domain.
The strategic intent of Tier 2 link building typically focuses on two goals:
- Funneling Authority and PageRank: By directing relevant secondary links to your Tier 1 pages, you aim to strengthen the authority and search presence of those intermediate documents, supporting the equity they pass downstream.
- Distributing Risk across Intermediate Assets: While building secondary tiers places a buffer between experimental links and your main domain, tiered link structures do not automatically protect a site from Google's spam policies. Search quality systems evaluate link patterns holistically, and low-quality or manipulative link schemes across intermediate tiers can still be ignored by algorithms like SpamBrain or trigger manual actions.
For secondary links to contribute effectively, search engines must first discover and evaluate them. When secondary pages remain undiscovered in deep web directories, their potential to pass PageRank or thematic signals remains dormant. Understanding how search engines handle secondary discovery is essential for managing tiered campaigns efficiently.
How Tier 1 and Tier 2 Links Work Together
To visualize tiered link relationships, consider how search engine crawlers traverse web graphs:
[Money Site] <--- (Tier 1: Editorial Placement) <--- (Tier 2: Supporting Resource / Web 2.0 / Contextual Link)When Googlebot crawls a Tier 2 URL, it parses the HTML and discovers the outbound hyperlink pointing to your Tier 1 asset. If the Tier 2 document is indexed, it becomes part of Google's searchable corpus, and its contextual relevance and PageRank contribute to the Tier 1 page's authority profile. Over time, recurring crawl signals prompt search engine bots to re-evaluate the Tier 1 URL, recognizing the secondary citations flowing into it.
Why Tier 2 Backlinks Often Remain Undiscovered or Unindexed
Unlike primary domain content that benefits from direct Search Console verification, XML sitemaps, and internal navigation, secondary backlinks face unique technical hurdles.
1. Understanding Discovery vs. Crawling vs. Indexing vs. Ranking
Google Search Central documentation clearly separates the lifecycle of a URL into distinct stages:
- Discovery: Google learns that a URL exists. This occurs via hyperlinks from known pages, XML sitemaps, or API submission. In Google Search Console, discovered URLs that have not yet been crawled appear under statuses like "Discovered – currently not indexed".
- Crawling: Googlebot allocates resources to fetch the HTML, assets, and code of the discovered URL.
- Indexing: Google renders and analyzes the page content, evaluates its canonical tags and uniqueness, and decides whether to store it in the search index. Crawling does not guarantee indexing.
- Ranking: If a page is indexed, search algorithms evaluate where and for which queries it appears based on hundreds of relevance and quality signals.
2. Crawl Budget and Depth Decay
Google defines crawl budget as the combination of crawl capacity limit (how many requests a host server can sustain without latency) and crawl demand (how popular and fresh the content is). Third-party platforms, Web 2.0 hosts, and public forum directories often host millions of orphaned pages. Googlebot rarely expends crawl capacity on orphan pages buried four, five, or six clicks deep from a platform's root directory.
3. Content Quality and Evaluation Thresholds
If a secondary page consists of thin, auto-generated, or duplicated content, Googlebot may crawl the page and immediately discard it from indexing. While unindexed pages may occasionally be crawled and their outbound links recorded in raw crawl graphs, pages that fail indexation quality thresholds cannot reliably pass full PageRank or anchor relevance.
4. Technical Server Responses and Directives
Many secondary web properties inadvertently block crawlers. In our technical guide on HTTP response signals and crawl frequency, we analyzed how server status codes dictate crawler revisiting behavior. If a secondary host returns 5xx server timeouts, extensive redirect chains, or serves a noindex robots directive, search engine bots halt indexation immediately.
Common Types of Tier 2 Backlinks
Different backlink formats present distinct discovery hurdles based on host architecture and editorial constraints:
| Backlink Type | Host Architecture | Primary Discovery Hurdle | Typical Indexation Behavior |
|---|---|---|---|
| Web 2.0 Blogs (Medium, Blogger, WordPress.com) | Subdomains or user directories | Orphaned status; lack of internal links from the main domain | Variable (depends on host quality and external crawl prompts) |
| Secondary Guest Posts & Editorial Mentions | Established root domains | Deep category archive placement or pagination decay | High (benefits from host domain's natural crawl budget) |
| Profile & Portfolio Links | User account subdirectories | Frequently restricted by noindex directives or login walls |
Low (frequent crawl blocks) |
| Contextual Community & Forum Threads | Threaded discussions | Fast archive decay; pagination depth | Moderate to Low |
| Business Citations & Directories | Database-driven listing directories | Template duplication across regional listings | Moderate (depends on platform editorial standards) |
How to Index Tier 2 Backlinks: A Practical Step-by-Step Workflow
To maximize the discovery and indexation rate of your secondary backlinks, follow this systematic framework:
Step 1: Sanitize and Normalize Your URL Dataset
Before submitting any backlink URLs, sanitize your list. Strip tracking parameters (such as #ref or ?utm_source), whitespace, and protocol fragments. Ensure all URLs reflect the correct canonical version (e.g., verifying https:// vs http:// and www vs non-www).
Step 2: Conduct an HTTP Status and Directive Audit
Run your backlink list through an HTTP header checker to ensure each target returns a clean 200 OK. Identify and resolve:
- 404 Not Found: The post was removed, unpublished, or flagged by the platform.
- 301/302 Redirects: Update your database to point directly to the final destination URL rather than the redirect initiator.
- Robots Directives: Inspect page source code for
<meta name="robots" content="noindex">orX-Robots-Tag: noindexHTTP headers. No submission service or tool can index a document that explicitly disallows indexation.
Step 3: Establish Internal Link Traversal
If you control the secondary properties (such as owned subdomains, Web 2.0 assets, or satellite blogs):
- Interlink Supporting Assets: Contextually link relevant secondary posts to one another to eliminate orphan page status and allow search crawlers to traverse the cluster.
- Maintain RSS Feeds: Ensure secondary blogs produce an active RSS/Atom feed that can be discovered by syndication feeds and aggregators.
Step 4: Leverage Proactive URL Submission Workflows
For large backlink datasets, waiting for organic crawler discovery through deep web links can result in prolonged delays. Proactive URL submission workflows systematically notify search engine crawlers of the URL's existence, prompting Googlebot to schedule an HTTP fetch.
For a detailed breakdown of sequential scheduling and submission mechanisms, consult our foundational guide on how to index backlinks in Google fast.
How to Prioritize and Process Bulk Backlink Lists
When managing hundreds or thousands of secondary links, avoid unstructured batch dumps. Structure your submission pipeline using logical prioritization:
- Prioritize Commercial Tier 1 Destinations: Focus first on Tier 2 links that point to Tier 1 pages targeting high-priority commercial keywords.
- Process Established Host Domains First: Submit links hosted on authoritative platforms before lower-trust domains, as established hosts have higher crawl capacity limits and respond faster to bot requests.
- Prioritize Fresh URLs: URLs published recently benefit from prompt submission before host platforms move them deeper into paginated archive pages.
Common Tier 2 Indexing Mistakes to Avoid
- Submitting Low-Quality or Spun Content: Prompting Googlebot to crawl automated, unreadable text often leads to immediate quality rejection. Ensure secondary content meets minimum readability and thematic relevance standards.
- Uncontrolled Submission Blasts: Submitting thousands of URLs simultaneously through unmonitored channels can trigger rate-limiting or automated security protections on host servers.
- Expecting Guaranteed Indexation: While third-party indexing workflows prompt crawlers to fetch documents, search engines retain complete algorithmic discretion regarding whether to index and rank the content.
How to Monitor Backlink Discovery and Indexing
Accurate monitoring requires reliable search verification methods:
1. URL-Specific "site:" Operator Searches
To verify if a specific URL is in Google's search index, enter the exact URL preceded by the site: operator:
site:example.com/tier2-article-path/If the URL appears in the search snippet results, it is confirmed indexed in Google's database.
2. Monitoring Tier 1 Performance in Google Search Console
Track the Tier 1 destination pages in Google Search Console. As secondary links are crawled and recognized, monitor changes in impressions and average position for target query clusters on your primary site.
Note on Google Cache: Google officially retired the public "cache:" search operator and cached page links. Do not rely on cache checks for indexing verification; use the URL inspection tool (for owned assets) or direct search queries.
Where an Indexing Service Fits into a Tier 2 Workflow
For practitioners managing multi-tier link campaigns at scale, manual submission is impractical. Dedicated URL processing services like Your Indexer help streamline the discovery phase.
Rather than waiting weeks for search engine bots to encounter secondary links organically, Your Indexer organizes URLs into structured queues and routes them through reliable indexing provider APIs. This prompts crawlers to schedule HTTP requests to deep backlink locations.
If you have a batch of new citations, profile links, or Tier 2 supporting articles ready for processing, explore our credit packages on the Pricing Page—ranging from a $2 Trial (110 credits) to larger Agency tiers, featuring pay-as-you-go credits without recurring commitments.
Important Note: An indexing service prompts search engine bots to crawl submitted URLs. Final indexation decisions depend entirely on Google's evaluation of page quality, server headers, and algorithmic relevance.
Frequently Asked Questions
What are Tier 2 backlinks?
Tier 2 backlinks are hyperlinks that point directly to your primary (Tier 1) backlink pages rather than your money site. They are built to strengthen the authority and PageRank of Tier 1 assets.
Does tiered link building protect my site from Google penalties?
No. While tiered link building isolates direct anchor text velocity on your primary domain, search engine algorithms evaluate broad link patterns. Manipulative link schemes, even when deployed across intermediate tiers, can be flagged by algorithmic spam systems.
Why are my Tier 2 backlinks not indexing?
Common reasons include placement deep within orphaned directories, low domain crawl budget, thin or duplicate content, and technical directives such as noindex tags or 5xx server errors.
Can any indexing service guarantee 100% indexing?
No legitimate service can guarantee Google indexing. Indexing services prompt search engine bots to discover and crawl submitted URLs; the ultimate decision to index rests with search engine algorithms.
Do unindexed backlinks pass any value?
Pages that are not indexed cannot pass search visibility or contextual anchor text equity through the standard search index. However, search crawlers may still traverse unindexed pages to discover linked documents.
Conclusion: Engineering Effective Secondary Link Discovery
Tier 2 backlinks only fulfill their role when search engines can discover, crawl, and evaluate them. By focusing on clean URL hygiene, verifying HTTP status codes, avoiding low-effort content, and leveraging structured submission workflows, you can build an efficient, scalable tiered linking strategy.
Speed Up Your Backlink Indexing Today
Stop waiting weeks for search engines to discover your high-value backlink URLs. YourIndexer processes links sequentially with automated verification.
Start Indexing Free →